CMSDAS Pre-Exercise 1: Unix basics
Overview
Teaching: 25 min
Exercises: 5 minQuestions
How do I get started with Unix?
How do I navigate the filesystem?
How do I manipulate files and folder?
Objectives
Setup a working Unix environment on your laptop.
Learn how to use folders and files in Unix.
Submit your answers
Work through the Question 1.x boxes on this page, then enter all your answers in the CMSDAS@LPC2027 answer form for Episode 1. You can resubmit at any time; we keep your latest answers. Stuck? Ask on Mattermost.
All CMSDAS@LPC 2027 participants should answer the questions in these exercises. Each episode has its own section in the answer form, linked in the box above.
The rest of the pre-exercises take place in Unix. If you have never used it, work through the HEP Software Foundation training, up to at least “3. Working With Files and Directories.”
Question 1.1
Check that you have a working Unix shell on your personal laptop. Copy-and-paste the following into your shell:
echo "$(whoami) $(date)"This prints your username followed by the current date and time. Enter the output in the answer form.
Key Points
Unix is the primary OS used in HEP, CMS included.
CMSDAS Pre-Exercise 2: Using the cmslpc cluster
Overview
Teaching: 0 min
Exercises: 30 minQuestions
How do I log in to the cmslpc cluster?
How do I run commands and edit files on cmslpc?
How do I copy files from EOS?
Objectives
Log in to cmslpc with kerberos and SSH.
Run a script and edit a file on cmslpc.
Copy a file from EOS to your nobackup area.
Submit your answers
Work through the Question 2.x boxes on this page, then enter all your answers in the CMSDAS@LPC2027 answer form for Episode 2. You can resubmit at any time; we keep your latest answers. Stuck? Ask on Mattermost.
Introduction
Your laptop can only do so much: CMS analyses run over far more data than fits on it.
In this episode you will use the cmslpc computing cluster at Fermilab, which you will use throughout CMSDAS and possibly for your own analysis.
Notes for CERN lxplus users are included where things differ.
The basics
cmslpc has interactive nodes, which you log in to with SSH, and many more worker nodes for large-scale batch computing.
The nodes run AlmaLinux 9 (el9), a free OS compatible with Red Hat Enterprise Linux.
Every user gets three storage areas:
| Area | Path | Size | Notes |
|---|---|---|---|
| Home | /uscms/home/<username> |
3 GB | Small: keep only config files here |
| nobackup | ~/nobackup (links to /uscms_data/d[1-3]/<username>) |
200 GB | Your main work area; not backed up |
| EOS | /store/user/<username> |
2 TB | Special filesystem, see below |
lxplus is set up similarly, with different paths and quotas. lxplus.cern.ch points to AlmaLinux 9 nodes.
Logging in
cmslpc uses kerberos for authentication and SSH for login.
If you have never logged in from this computer, first set up krb5.conf and ~/.ssh/config following the cmslpc prerequisites.
(New to SSH? See the HSF SSH lesson.)
Then, on your own computer, get a kerberos ticket and log in:
kinit <YourUsername>@FNAL.GOV        # lxplus: kinit <YourUsername>@CERN.CH
ssh -Y <YourUsername>@cmslpc-el9.fnal.gov   # lxplus: ssh -Y <YourUsername>@lxplus.cern.ch
kinit asks for your Fermilab kerberos password and is valid for 24 hours.
If you see a welcome message and a prompt, you’re in: commands now run on cmslpc.
If you get an error, re-check your kerberos configuration, then post the error on Mattermost.
Running simple commands on cmslpc
These steps only work on cmslpc-el9. Experienced users can breeze through, but please still submit your answers so we can follow everyone’s progress.
Make a folder for your CMSDAS work, copy in the runThisCommand.py script, and run it with these exact arguments (copy-and-paste them):
mkdir ~/nobackup/cmsdas
cd ~/nobackup/cmsdas
cp ~cmsdas/preexercises/runThisCommand.py .
python3 runThisCommand.py "asdf;klasdjf;kakjsdf;akjf;aksdljf;a" "sldjfqewradsfafaw4efaefawefzdxffasdfw4ffawefawe4fawasdffadsfef"
It prints your username followed by a string unique to you. For example, for user gbenelli:
success: gbenelli toraryyv
Seeing an error instead?
Error: You must provide the secret key: you left out the two arguments.Error: You didn't paste the correct input string: the arguments were mistyped; copy-and-paste them.No such file or directoryorUnknown user: you are not on cmslpc-el9 (for example, you ran it on your laptop).
Question 2.1
Enter the alphanumeric string unique to your username in the answer form.
Editing files on cmslpc
You’ll edit code on cmslpc constantly. Common options:
- A terminal editor directly on cmslpc:
nano(simplest),vim, oremacs -nw(plainemacsopens a slow GUI over SSH). - A desktop editor such as VS Code with a remote/SSH plugin, which shows your cmslpc folder as if it were local.
- Editing on your laptop and copying with
scp/sftp.
For this exercise, use a terminal editor on cmslpc. (New to vim? Try this interactive tutorial.)
Copy the editThisCommand.py script:
cd ~/nobackup/cmsdas
cp ~cmsdas/preexercises/editThisCommand.py .
Open it (e.g. nano editThisCommand.py). Line 11 deliberately raises an error. Add a # at the start of the line to turn it into a comment:
#raise RuntimeError("You need to comment out this line with a #")
Save and quit (nano: ctrl+o, ctrl+x; vim: i to type, then Esc and :wq; emacs: ctrl+x ctrl+s, ctrl+x ctrl+c), then run:
./editThisCommand.py
If the edit worked, you’ll see a line like success: gbenelli 0x6D0DB4E0.
If you see RuntimeError: You need to comment out this line with a #, the edit wasn’t saved.
Question 2.2
Enter the line beginning with “success”, printed by
./editThisCommand.py, in the answer form.
Using the EOS filesystem
EOS is your largest storage area, but it is not a normal Unix folder and has its own commands.
Files on EOS are named by logical filenames (LFNs), which start with /store/....
The essential commands are below; see Using EOS at LPC for everything else.
| Unix | EOS on cmslpc | Example |
|---|---|---|
ls |
eosls |
eosls -alh /store/user/cmsdas/preexercises/ |
mkdir, mv |
eosmkdir, eosmv |
|
cp |
xrdcp |
xrdcp root://cmseos.fnal.gov//store/user/<file> . |
The eos* commands are cmslpc shortcuts for eos root://cmseos.fnal.gov ...; run alias eosls to see the full command, which you need on other clusters.
In xrdcp, the root://cmseos.fnal.gov prefix names the EOS instance. lxplus has several, such as root://eoscms.cern.ch (CMS data) and root://eosuser.cern.ch (user data).
Question 2.3
Copy a small file from EOS to your nobackup area. It holds 10,000 simulated $Z\rightarrow\mu^+\mu^-$ events in the CMS NanoAOD format, and later episodes use it, so keep it.
cd ~/nobackup/cmsdas/
xrdcp root://cmseos.fnal.gov//store/user/cmsdas/preexercises/DYJetsToLL_M50_NANOAOD.root .
ls -lh DYJetsToLL_M50_NANOAOD.root
How big is the file? (It’s the large number in the
ls -lhoutput.) Enter it in the answer form.
Key Points
Log in with
kinit <username>@FNAL.GOVfollowed byssh -Y <username>@cmslpc-el9.fnal.gov.Use
~/nobackupfor your work; your home directory is small.EOS has its own commands (
eosls,eosmkdir,xrdcp) and addresses files by LFNs like/store/user/....
CMSDAS Pre-Exercise 3: ROOT and python basics
Overview
Teaching: 0 min
Exercises: 60 minQuestions
How do I set up ROOT and python on cmslpc?
How do I inspect a NanoAOD file?
How do I make a quick plot with pyROOT?
Objectives
Learn how to use ROOT and python
Use ROOT and python to inspect a CMS NanoAOD file
Submit your answers
Work through the Question 3.x boxes on this page, then enter all your answers in the CMSDAS@LPC2027 answer form for Episode 3. You can resubmit at any time; we keep your latest answers. Stuck? Ask on Mattermost.
Python and ROOT
Python and ROOT are two of the most important software tools in HEP. Before starting:
- Python: if you’ve never used it, work through the Software Carpentry python lesson. If you know the basics, carry on; you’ll learn by doing.
- ROOT: work through the ROOT student course up to at least 02-tfile-read-write-ttree. The easiest way is the SWAN button, which runs the notebooks in your browser on CERN’s analysis service.
Inspect a NanoAOD file with ROOT
Now let’s look at real CMS data on cmslpc. Log in as in Episode 2.
A fresh cmslpc login has no ROOT and an old python. The LCG releases provide both; run this once per login:
source /cvmfs/sft.cern.ch/lcg/views/LCG_106a/x86_64-el9-gcc14-opt/setup.sh
Open the NanoAOD file you copied in Episode 2 with ROOT’s C++ interpreter (-l skips the slow splash screen; type .q to quit):
cd ~/nobackup/cmsdas
root -l DYJetsToLL_M50_NANOAOD.root
At the ROOT prompt, list the file’s contents:
root [1] _file0->ls()
TFile**		DYJetsToLL_M50_NANOAOD.root
 TFile*		DYJetsToLL_M50_NANOAOD.root
  KEY: TTree	Events;1	Events
The file contains one TTree, Events. Count its entries:
root [2] Events->GetEntries()
(long long) 10000
Events->Print() lists every branch, but NanoAOD has a branch for every CMS trigger, so the list is very long (over 1600 branches). Filter it instead, for example to muon branches only:
root [3] Events->Print("Muon*")
...
*Br    0 :Muon_dxy  : Float_t dxy (with sign) wrt first PV, in cm            *
*Br    1 :Muon_dxyErr : Float_t dxy uncertainty, in cm                       *
...
Question 3.1
TTree::GetEntries(const char *selection)returns the number of events passing a selection (written in C++). Count the events with at least two reconstructed muons:root [4] Events->GetEntries("nMuon >= 2")Enter the number in the answer form.
Plotting with pyROOT
pyROOT lets you use ROOT from python with almost the same commands as in C++.
On cmslpc, with the LCG setup above, start python3 (ctrl-d or exit() to quit) and reopen the file:
import ROOT
f = ROOT.TFile("DYJetsToLL_M50_NANOAOD.root", "READ")
f.ls()
TTree::Draw(varexp, selection) is the fastest way to plot from a TTree: varexp is what to plot (a branch or an expression) and selection filters the events.
Let’s plot the mass of the generator-level Z bosons, i.e. the “truth” particles from the event generator, before detector simulation.
GenPart_mass holds the mass of each generated particle, and GenPart_pdgId its PDG ID (23 for a Z boson):
events = f.Get("Events")
c = ROOT.TCanvas()
events.Draw("GenPart_mass", "GenPart_pdgId==23")
c.Draw()
A plot should appear with a mean close to the Z mass, 91.1876 GeV.
No window? Check that you have an X server on your computer and logged in with ssh -Y (see the cmslpc instructions).
Question 3.2: Z mass plot
The plot has a “stat box” with basic information about the histogram. Enter the mean of the distribution in the answer form.
Key Points
ROOT and python are two key software tools in HEP.
Many CMS analyses use the NanoAOD format, which are simple ROOT ntuples that can be analyzed with standalone ROOT or pyROOT.
There are numerous ways to use ROOT, including the built-in C++ interpreter (Cling), pyROOT, Jupyter notebooks, compiled C++, and more.
CMSDAS Pre-Exercise 4: Using git
Overview
Teaching: 0 min
Exercises: 30 minQuestions
How do I setup git on my computer/cluster?
How do I collaborate using GitHub?
Objectives
Setup your git configuration for a given computer.
Learn how to make and commit changes to a git repository.
Learn how to create a pull request on GitHub.
Submit your answers
Work through the Question 4.x boxes on this page, then enter all your answers in the CMSDAS@LPC2027 answer form for Episode 4. You can resubmit at any time; we keep your latest answers. Stuck? Ask on Mattermost.
Introduction
This exercise walks you through the standard GitHub “fork and pull” workflow: copy a repository, make a change, and propose it back as a pull request. It is a condensed version of the CMSGitTutorial. If you’ve never used git or other version control, read at least the first set of its slides first.
Prerequisite
You need a GitHub account with SSH keys set up, as described in the setup instructions. Choose your username wisely: it appears on all your contributions to CMS code. If yours is something like
edgelord1337, consider changing it or making a second account.
Configure git
Tell git who you are. Do this on every computer you develop on (cmslpc, your laptop, …), replacing the [brackets] with your details and GitHub username:
git config --global user.name "[Name]"
git config --global user.email [Email]
git config --global user.github [Account]
Check the result with cat ~/.gitconfig; it should contain a [user] section with these three values.
Optional settings
# Your preferred editor for commit messages
git config --global core.editor [your preferred text editor]
# Make `git push origin` push the current branch
git config --global push.default current
# `git lol`: a compact, graphical log
git config --global alias.lol 'log --graph --decorate --pretty=oneline --abbrev-commit'
# Shortcuts such as `git clone github:GitHATSLPC/GitHATS.git`
git config --global url."git@github.com:".insteadOf github:
git config --global url."ssh://git@gitlab.cern.ch:7999/".insteadOf gitlab:
The GitHub interface
Open the GitHATSLPC/GitHATS repository and click around:
- Top left: Code, Issues, Pull Requests, Actions, Projects, Wiki, Security, Insights

- Top right: Notifications, Star, Fork
- On the Code page: commits, branches, releases, contributors

Fork and clone
Click Fork (top right) on GitHATSLPC/GitHATS to make your own copy under your GitHub account. Then clone your fork, on cmslpc or your laptop, and look around:
mkdir scratch
cd scratch
git clone git@github.com:[user]/GitHATS.git
cd GitHATS
ls -a
git branch -a
Expected output
ls -ashows the files plus a.gitfolder, which holds the full history of the repository:. .. .git README.md standard_model.md
git branch -ashows you are onmain, the repository’s default branch, plus the branches on GitHub:* main remotes/origin/HEAD -> origin/main remotes/origin/atlas_discovery remotes/origin/cms_discovery remotes/origin/dune_discovery remotes/origin/main
Remotes and synchronizing
A remote is a copy of the repository elsewhere. git clone creates one called origin, pointing to your fork.
Add a second remote, traditionally called upstream, pointing to the original repository:
git remote add upstream git@github.com:GitHATSLPC/GitHATS.git
git remote -v
Expected output
origin    git@github.com:[user]/GitHATS.git (fetch)
origin    git@github.com:[user]/GitHATS.git (push)
upstream  git@github.com:GitHATSLPC/GitHATS.git (fetch)
upstream  git@github.com:GitHATSLPC/GitHATS.git (push)
Before making changes, bring your copy up to date with upstream (someone may have changed it), and push any updates to your fork. Here, both will just report that everything is up to date.
git pull upstream main    # same as: git fetch upstream main; git merge upstream/main
git push origin main
Make and commit a change
Make your changes on a separate topic branch. This keeps main in sync with upstream and lets you work on several changes at once.
git checkout -b MyBranch
Edit standard_model.md and add a row for a new particle, the Giton: symbol G, spin 2, charge 0, mass 750 GeV.
(Any resemblance to real or imaginary particles is entirely coincidental.)
Look at what changed:
git status      # which files changed
git diff        # what changed in them
Expected output
git statuslistsmodified: standard_model.mdunder “Changes not staged for commit”.git diffshows your new line with a+:+| Giton | G | 2 | 0 | 750 |
Stage the change (choose what goes into the next commit), commit it to your local repository, and push the branch to your fork:
git add standard_model.md
git commit -m "add Giton to standard model"
git push origin MyBranch
Expected output
The push ends with a link for opening a pull request:
remote: Create a pull request for 'MyBranch' on GitHub by visiting:
remote:      https://github.com/[user]/GitHATS/pull/new/MyBranch
...
 * [new branch]      MyBranch -> MyBranch
Make a pull request
A pull request (PR) proposes your change for inclusion in another repository.
Open the link printed by git push (or your fork’s page on GitHub). You can send a PR to any fork and branch of the repository:
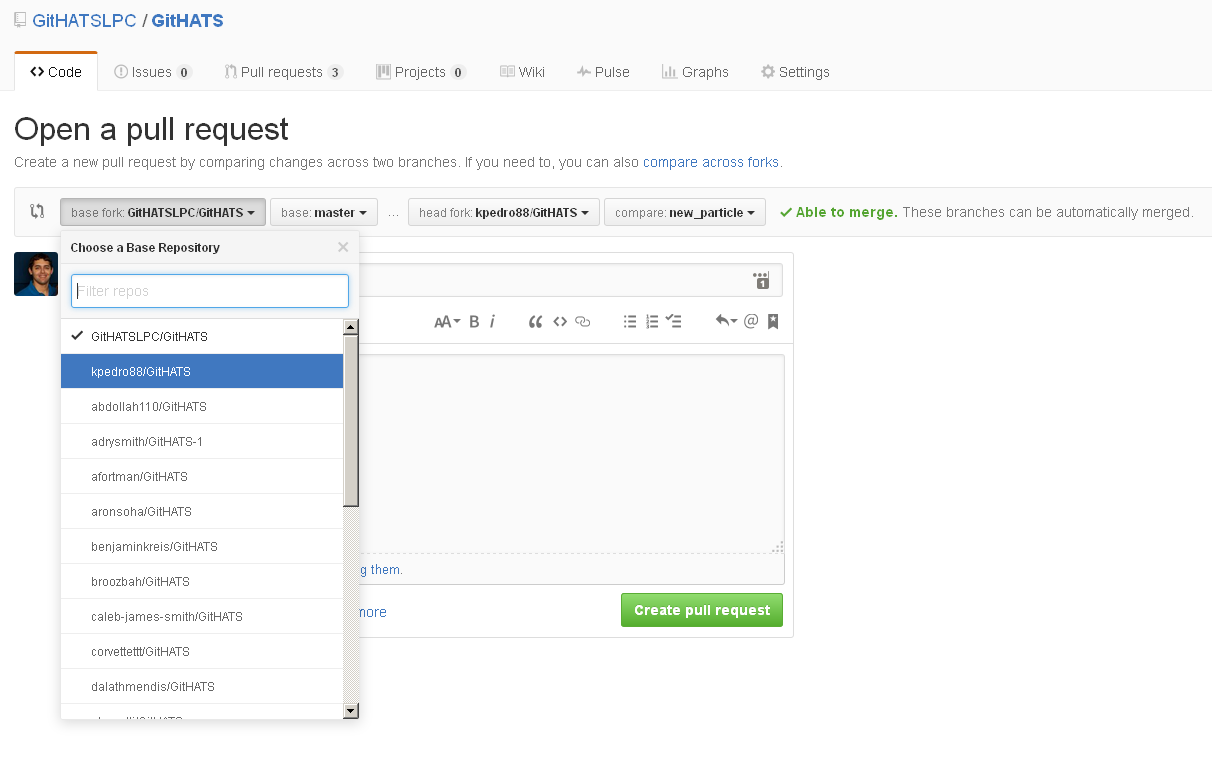
Send it to the main branch of the upstream repository (GitHATSLPC):
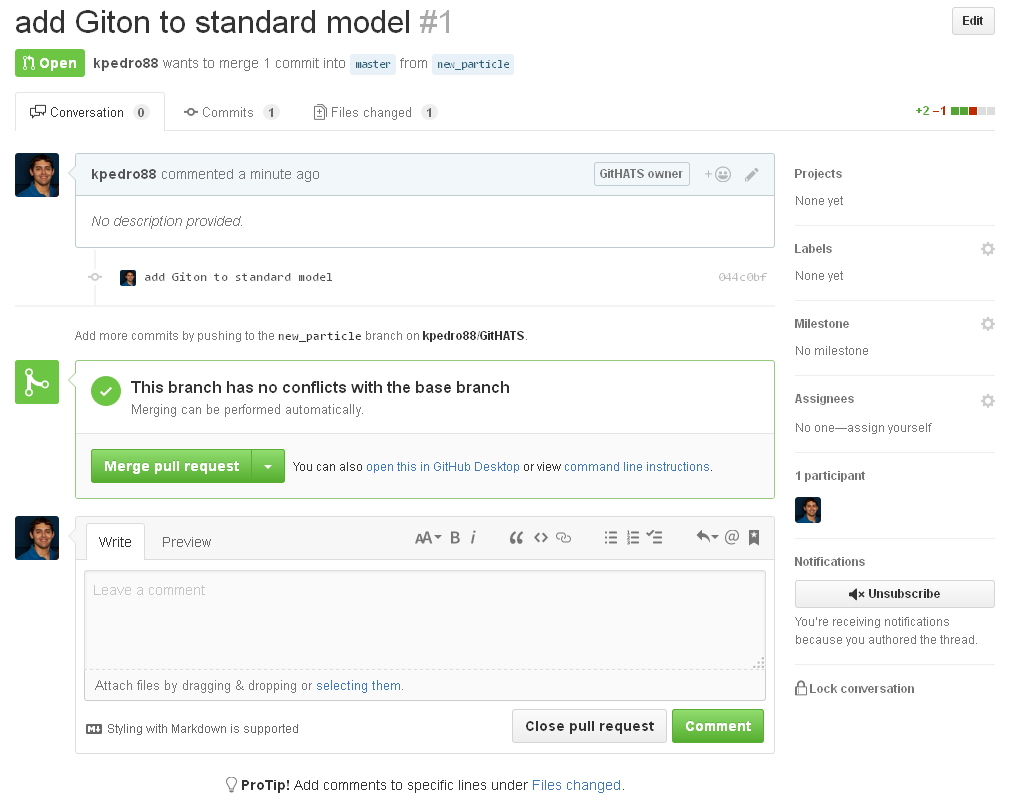
Question 4.1
Enter the link to your pull request in the answer form.
Optional: go further
- To practice merging, send a pull request from
MyBranchto your own fork’smainbranch and merge it.- Not covered here: rebasing, cherry-picking, undoing changes, and CMSSW-specific git usage. Learn more from the CMSGitTutorial, the HSF training modules, and the Pro Git book.
Key Points
Interact with your git configuration using
git config --global.Use the
git clonecommand to obtain a local copy of a git repository.Add and interact with new remotes using the
git remotecommand.Use the
addandcommitcommands to add changes to the local repository.The
pullandpushcommands will transfer changes between the remote and local copies of the repository.
CMSDAS Pre-Exercise 5: CMSSW basics
Overview
Teaching: 0 min
Exercises: 60 minQuestions
What is CMSSW, and when do I need it?
How do I set up a CMSSW release?
How do I compile and run a CMSSW job?
Objectives
Setup a CMSSW environment
Use git to download an example EDAnalyzer
Run a CMSSW job on real dimuon data to plot the Z peak
Submit your answers
Work through the Question 5.x boxes on this page, then enter all your answers in the CMSDAS@LPC2027 answer form for Episode 5. You can resubmit at any time; we keep your latest answers. Stuck? Ask on Mattermost.
CMSSW
CMSSW is CMS’s software framework for processing and analyzing data. It is made of many C++ modules that, for example:
- turn RAW detector data into C++ objects;
- reconstruct hits and physics objects (tracks, electrons, muons, jets, …);
- load calibrations from databases and apply them;
- run event generators like Pythia and MadGraph5_aMC@NLO.
CMS stores events in a chain of formats, each smaller than the last: RAW (straight from the detector) → RECO (reconstructed) → AOD → MiniAOD → NanoAOD. The early formats are mostly archived on tape; MiniAOD and NanoAOD are usually on disk. You’ll learn to find them in the next episode.
Do you need CMSSW?
NanoAOD is a plain ROOT format that does not need CMSSW, and many analyses now run entirely outside it, using ROOT, RDataFrame, or scientific python. You do need CMSSW if your analysis needs information missing from NanoAOD (for example, long-lived particle searches often need tracker or calorimeter hits), and for most detector, trigger, and POG work.
Setting up CMSSW
CMSSW comes in releases, fixed snapshots of the code. A release name such as CMSSW_13_0_10 gives the major cycle (13), a feature release (0), and a bug-fix release (10).
CMSSW_13_0_X was used for 2023 data taking and for NanoAODv12. See the release schedule for the full list.
Start from a fresh login
Software environments don’t mix: if the LCG setup from the previous episode (or conda, etc.) is active in the same session, CMSSW will break. Log out and back in to cmslpc first.
Create a CMSSW area in your work folder. This makes a folder CMSSW_13_0_10_cmsdas; your code goes in its src subfolder.
cd ~/nobackup/cmsdas
source /cvmfs/cms.cern.ch/cmsset_default.sh
scram project -n "CMSSW_13_0_10_cmsdas" CMSSW_13_0_10
cd CMSSW_13_0_10_cmsdas/src
cmsenv
cmsenv sets up the release in your current shell; run it again (from inside src) every time you log in.
Tip: add the source /cvmfs/cms.cern.ch/cmsset_default.sh line to your ~/.bash_profile so it runs at every login.
cmsenv also defines handy variables, such as $CMSSW_BASE, which points to your CMSSW folder.
Question 5.1
Print the location of your CMSSW area, and enter it in the answer form:
echo $CMSSW_BASE
Question 5.2
Each release comes with external tools, such as the Pythia generator. Print the Pythia version in your release and enter the version number in the answer form:
scram tool info pythia8
Getting the example code with git
Configure git on cmslpc as in Episode 4, if you haven’t already.
Then clone the example analysis. The cd matters: CMSSW expects code in src/<Package>/<SubPackage>.
cd $CMSSW_BASE/src
git clone git@github.com:FNALLPC/LearnCMSSW MyAnalysis/LearnCMSSW
If the clone fails, your SSH key is probably not set up on GitHub; see the setup instructions.
Question 5.3: git repo info
Cloning also set up a local git repository connected to the one on GitHub. Print the address of that remote repository:
cd $CMSSW_BASE/src/MyAnalysis/LearnCMSSW
git remote -v
Enter the first line of the output in the answer form.
Running a CMSSW job
Compile the code with scram, CMSSW’s build tool. (scram b -j4 uses 4 cores; don’t go higher on the shared interactive nodes.)
cd $CMSSW_BASE/src
scram b
CMSSW jobs are configured with python files and run with cmsRun.
The configuration MyAnalysis/LearnCMSSW/test/zpeak_cfg.py runs the ZPeakAnalyzer module (MyAnalysis/LearnCMSSW/plugins/ZPeakAnalyzer.cc), which reads dimuon events in MiniAOD format and fills some histograms:
cd $CMSSW_BASE/src/MyAnalysis/LearnCMSSW/test
cmsRun zpeak_cfg.py
The job takes about a minute and writes ZPeak.root. Open it and plot the Z peak:
root -l ZPeak.root
root [0] TH1D* dimuonMass = (TH1D*)_file0->Get("zpeak_analyzer/dimuonMass")
root [1] dimuonMass->Draw()
Question 5.4
What is the mean dimuon mass shown in the histogram’s stat box? Enter it in the answer form.
Key Points
CMSSW is CMS’s software framework for data processing.
The framework consists of lots of C++ modules, which are configured using python.
CMSSW jobs are launched using commands like
cmsRun myCfg.pyWe provide an example EDAnalyzer and cfg.py file for plotting a Z peak directly from a MiniAOD file.
Analyzing simple ROOT ntuples like NanoAOD does not need CMSSW!
CMSDAS Pre-Exercise 6: Using the grid
Overview
Teaching: 0 min
Exercises: 60 minQuestions
How do I find CMS data on the grid?
How do I run jobs on the grid with CRAB?
How do I publish and retrieve my CRAB output?
Objectives
Learn how to find CMS data on the grid
Launch a MC (Monte Carlo) generation job using CRAB
Launch a MiniAOD processing job using CRAB
Optional, but start early
This episode is not required to register for CMSDAS, but we encourage everyone to do it: any real CMS analysis uses the grid. It takes only a few hours of work, but storage requests and grid jobs can take days, so set aside about a week.
Submit your answers
Work through the Question 6.x boxes on this page, then enter all your answers in the CMSDAS@LPC2027 answer form for Episode 6. You can resubmit at any time; we keep your latest answers. Stuck? Ask on Mattermost.
Before you start
You need:
- a cmslpc account, a grid certificate, and CMS VO membership (see the setup instructions);
- write access to
T3_US_FNALLPC, i.e. your EOS area/store/user/<username>linked to your grid certificate (checked below).
lxplus users who already know CRAB can do everything at CERN instead. After CMSDAS, you can use the same steps to write to your university’s Tier 2 or Tier 3 storage.
If you get stuck, ask on Mattermost or email CMSDASATLPC@fnal.gov with a detailed description of the problem. Outside CMSDAS, see the CRAB troubleshooting twiki or the Computing Tools forum on cms-talk.
Finding data on the grid
CMS data is spread over computing sites around the world (Tier 1, 2, and 3). To find it, use the Data Aggregation Service (DAS), not to be confused with this school!
Open the DAS website (your browser needs your grid certificate; you may have to accept a security warning) and search for:
dataset dataset=/DYJetsToLL_M-50_TuneCP5_13TeV-madgraphMLM-pythia8/RunIISummer20UL18NanoAODv9-106X_upgrade2018_realistic_v16_L1v1-v1/NANOAODSIM
The first dataset says you’re searching for datasets; dataset=/DYJets... filters to this one. You should get exactly one result.
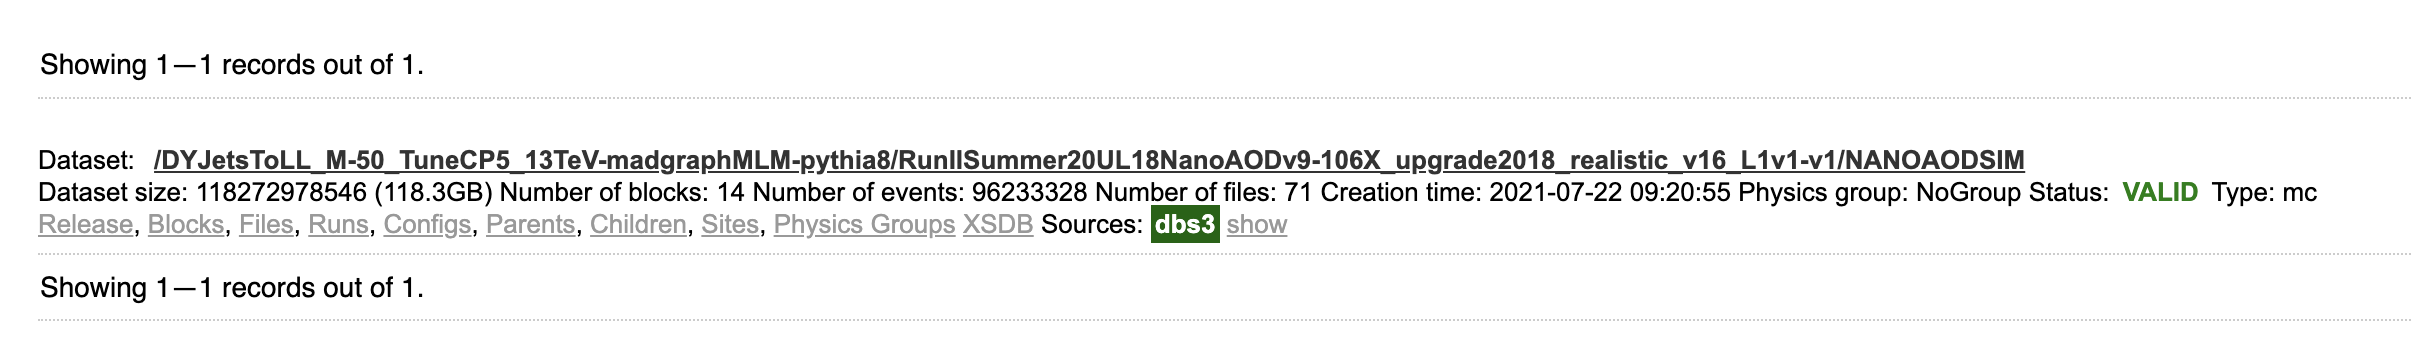
Click Files to list the files in the dataset: 71 files, mostly about 2 GB with about 2 million events each.
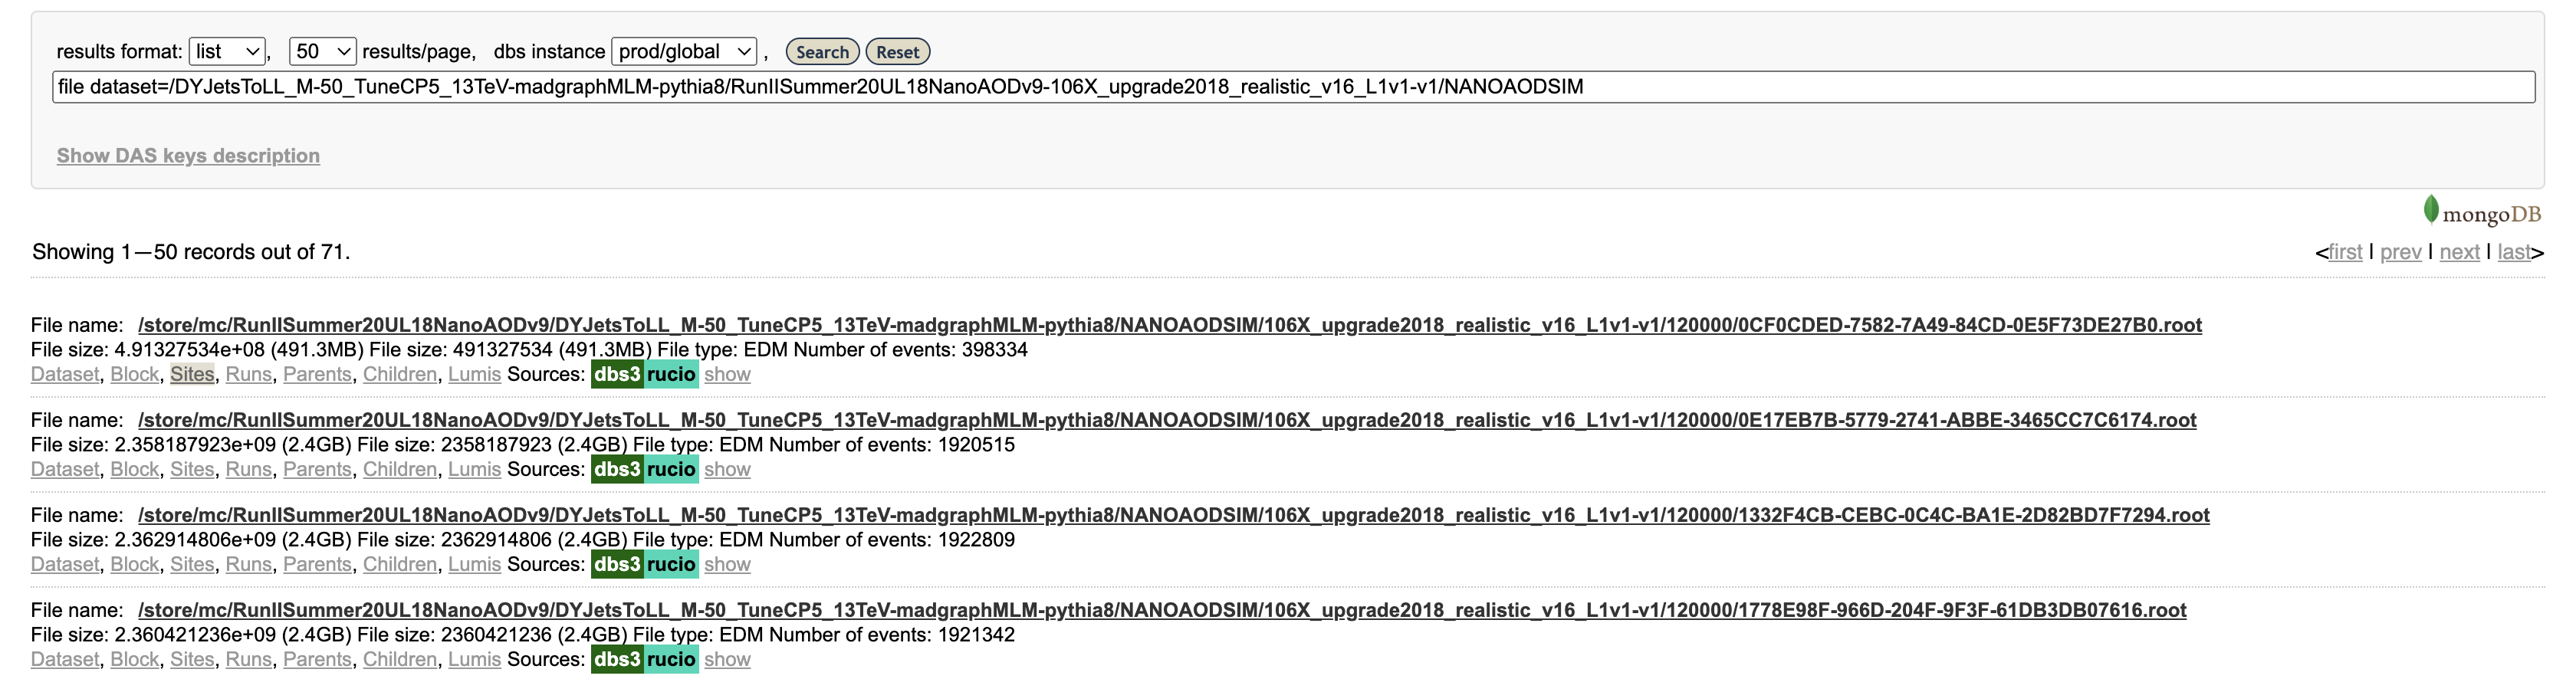
Click Sites for one file to see where it is stored, for example T1_US_FNAL_Disk, T2_US_MIT, and T2_US_Purdue. More on DAS: the DAS FAQ and WorkBookDataSamples.
Verify your grid certificate
Install your grid certificate on cmslpc-el9 too (see the setup instructions). Then log in to cmslpc-el9.fnal.gov, create a grid proxy, and inspect it:
voms-proxy-init -voms cms
voms-proxy-info -all | grep -Ei "role|subject"
The output should look like this:
subject   : /DC=ch/DC=cern/OU=Organic Units/OU=Users/CN=haweber/CN=713242/CN=Hannsjorg Weber/CN=2282089851
subject   : /DC=ch/DC=cern/OU=Organic Units/OU=Users/CN=haweber/CN=713242/CN=Hannsjorg Weber
attribute : /cms/Role=NULL/Capability=NULL
attribute : /cms/uscms/Role=NULL/Capability=NULL
No attribute : /cms/... line? Your CMS VO registration is probably incomplete; check the setup instructions, then ask on Mattermost.
Question 6.1
Enter your output of the command above in the answer form.
With a valid proxy, you can also query DAS from the command line with dasgoclient.
Question 6.2: DAS client
On cmslpc, find the number of events in a real collision dataset:
dasgoclient -query="dataset dataset=/JetHT/Run2018C-UL2018_MiniAODv2_NanoAODv9-v1/NANOAOD" -json | grep "nevents"Enter the number of events in the answer form.
Obtain a /store/user area
Your cmslpc account comes with EOS storage at /store/user/<username> (see Using EOS at LPC), and CRAB will write its output there.
But CRAB can only write there if the area is linked to your grid certificate. If you didn’t give your certificate in the cmslpc account application, file a CMS Storage Space Request. It can take up to one business day (Fermilab hours).
CRAB introduction
Downloading a whole dataset with xrdcp would quickly fill your quota. Instead, the CMS Remote Analysis Builder (CRAB) sends your CMSSW jobs to the grid, usually to CPUs at the site where the input data is stored, and copies the (much smaller) output to your /store/user area.
After this episode, we strongly recommend the full CRAB tutorial.
Set up CRAB
Set up a new CMSSW area for this exercise. CRAB comes with CMSSW: which crab should then print something like /cvmfs/cms.cern.ch/common/crab.
cd ~/nobackup/cmsdas/
scram project -n "CMSSW_13_0_13_mcgen" CMSSW_13_0_13
cd CMSSW_13_0_13_mcgen/src
cmsenv
Check that CRAB can write to your EOS area (with a valid proxy from voms-proxy-init -voms cms):
crab checkwrite --site=T3_US_FNALLPC
After a fair amount of output, it should end with:
Success: Able to write in /store/user/<username> on site T3_US_FNALLPC
Generate and publish a minimum-bias sample with CRAB
Next you’ll generate a small minimum-bias Monte Carlo (MC) sample, first locally and then on the grid.
A CMS MC job starts from a fragment, a short piece of python that configures the event generator inside CMSSW. Download a recent minimum-bias fragment:
cd $CMSSW_BASE/src
curl -s -k https://cms-pdmv-prod.web.cern.ch/mcm/public/restapi/requests/get_fragment/PPD-Run3Summer23GS-00003 --retry 3 --create-dirs -o Configuration/GenProduction/python/PPD-Run3Summer23GS-00003-fragment.py
Show the fragment
It sets up a module that runs Pythia inside CMSSW, plus Pythia settings:
import FWCore.ParameterSet.Config as cms

from Configuration.Generator.Pythia8CommonSettings_cfi import *
from Configuration.Generator.MCTunesRun3ECM13p6TeV.PythiaCP5Settings_cfi import *

generator = cms.EDFilter("Pythia8ConcurrentGeneratorFilter",
    maxEventsToPrint = cms.untracked.int32(1),
    pythiaPylistVerbosity = cms.untracked.int32(1),
    filterEfficiency = cms.untracked.double(1.0),
    pythiaHepMCVerbosity = cms.untracked.bool(False),
    comEnergy = cms.double(13600.),
    PythiaParameters = cms.PSet(
        pythia8CommonSettingsBlock,
        pythia8CP5SettingsBlock,
        processParameters = cms.vstring(
              'SoftQCD:inelastic = on'
       ),
        parameterSets = cms.vstring('pythia8CommonSettings',
                                    'pythia8CP5Settings',
                                    'processParameters',
                                    )
    )
)
Turn the fragment into a full CMSSW configuration with cmsDriver.py. (scram b first, so CMSSW knows about the new file.)
cd $CMSSW_BASE/src
scram b
cmsDriver.py Configuration/GenProduction/python/PPD-Run3Summer23GS-00003-fragment.py --python_filename cmsdas_minbias_cfg.py --eventcontent NANOAODGEN --step GEN,NANOGEN --datatier NANOAODSIM --customise Configuration/DataProcessing/Utils.addMonitoring --fileout file:cmsdas_minbias_nanogen.root --conditions 130X_mcRun3_2023_realistic_forMB_v1 --beamspot Realistic25ns13p6TeVEarly2023Collision --geometry DB:Extended --era Run3_2023 --no_exec --mc -n 20
This writes cmsdas_minbias_cfg.py; skim it to see how much cmsDriver.py wrote for you.
The job generates 20 events with Pythia (the GEN step) and saves the generated particles to a NanoAOD file (NANOGEN), skipping detector simulation to keep things fast.
Test locally
Always test a few events locally before sending jobs to the grid. This takes a few minutes and prints a lot of Pythia output:
cmsRun cmsdas_minbias_cfg.py
Question 6.3
What is the size of the output file
cmsdas_minbias_nanogen.root? Usels -lh, and enter it in the answer form.
Submit to CRAB
CRAB is configured with (once again!) a python file; see CRAB3ConfigurationFile for all the options. Download our config and submit it:
cd $CMSSW_BASE/src
wget fnallpc.github.io/cms-das-pre-exercises/code/cmsdas_mc_crab.py
crab submit -c cmsdas_mc_crab.py
Show the CRAB config
It runs 10 jobs of 20 events each and publishes the output as a dataset:
from WMCore.Configuration import Configuration
config = Configuration()

config.section_("General")
config.General.requestName = 'cmsdas_minbias_test0'
config.General.workArea = 'crabsubmit'

config.section_("JobType")
config.JobType.pluginName = 'PrivateMC'
config.JobType.psetName = 'cmsdas_minbias_cfg.py'
config.JobType.allowUndistributedCMSSW = True

config.section_("Data")
config.Data.outputPrimaryDataset = 'MinBias'
config.Data.splitting = 'EventBased'
config.Data.unitsPerJob = 20
NJOBS = 10  # This is not a configuration parameter, but an auxiliary variable that we use in the next line.
config.Data.totalUnits = config.Data.unitsPerJob * NJOBS
config.Data.publication = True
config.Data.outputDatasetTag = 'MinBias_TuneCP5_13p6TeV-pythia8_cmsdas2025_test0'

config.section_("Site")
config.Site.storageSite = 'T3_US_FNALLPC'
You may be asked for your grid certificate password. A successful submission ends with:
Success: Your task has been delivered to the prod CRAB3 server.
Task name: 231110_212908:<username>_crab_cmsdas_minbias_test0
Project dir: crabsubmit/crab_cmsdas_minbias_test0
Please use ' crab status -d crabsubmit/crab_cmsdas_minbias_test0 ' to check how the submission process proceeds.
Don’t delete the project directory
crabsubmit/crab_cmsdas_minbias_test0holds everything CRAB needs to manage your task. Jobs sometimes fail (site problems, network errors, …) and can be retried withcrab resubmit -d <project dir>, but only if the directory still exists. Don’t modify or delete it until the task is completely finished.
Monitor the task
Check the status of your task (see CRAB commands for others):
crab status -d crabsubmit/crab_cmsdas_minbias_test0
This shows how many jobs are in each state (idle, running, transferring, finished, failed, …) and links to monitoring web pages. Jobs usually take a few hours; take a break and check back. When the task is done, the output looks like this (abridged):
Status on the scheduler:    COMPLETED

Jobs status:                    finished            100.0% (10/10)

Publication status of 1 dataset(s):  done           100.0% (10/10)

Output dataset:         /MinBias/<username>-MinBias_TuneCP5_13p6TeV-pythia8_cmsdas2025_test0-<hash>/USER
Output dataset DAS URL: https://cmsweb.cern.ch/das/request?input=...&instance=prod%2Fphys03
...
The output files are in your EOS area, e.g. eosls /store/user/<username>/MinBias/MinBias_TuneCP5_13p6TeV-pythia8_cmsdas2025_test0/.
The Output dataset line is the name of your published dataset: congratulations, your first CMS dataset!
Note that CRAB gives each job its own random-number seed. Running cmsRun cmsdas_minbias_cfg.py ten times yourself would give ten identical files.
Question 6.4
Enter the name of the dataset you published in the answer form.
Processing MiniAOD with CRAB
Now run the ZPeakAnalyzer from Episode 5 on real data with CRAB. It uses the Episode 5 release, so log out, log back in, and set it up:
cd ~/nobackup/cmsdas/CMSSW_13_0_10_cmsdas/src
cmsenv
wget fnallpc.github.io/cms-das-pre-exercises/code/cmsdas_zpeak_crab.py
Show the CRAB config
import os
from WMCore.Configuration import Configuration
config = Configuration()

config.section_("General")
config.General.requestName = 'cmsdas_zpeak_test0'
config.General.workArea = 'crabsubmit'

config.section_("JobType")
config.JobType.pluginName = 'Analysis'
config.JobType.psetName = os.path.expandvars('$CMSSW_BASE/src/MyAnalysis/LearnCMSSW/test/zpeak_cfg.py')
config.JobType.allowUndistributedCMSSW = True

config.section_("Data")
config.Data.inputDataset = '/DoubleMuon/Run2016C-03Feb2017-v1/MINIAOD'
config.Data.inputDBS = 'global'
config.Data.splitting = 'LumiBased'
config.Data.unitsPerJob = 50
config.Data.lumiMask = 'https://cms-service-dqmdc.web.cern.ch/CAF/certification/Collisions16/13TeV/Cert_271036-275783_13TeV_PromptReco_Collisions16_JSON.txt'
config.Data.runRange = '275776-275782'

config.section_("Site")
config.Site.storageSite = 'T3_US_FNALLPC'
Compared with the MC config, two settings are new:
runRangeprocesses only a few runs, to save time and CO2;lumiMasklists the runs and lumisections certified as good for analysis. Each detector group marks data as bad when it had problems, for example a wrong HCAL photomultiplier voltage.
Submit the task and check on it as before:
crab submit -c cmsdas_zpeak_crab.py
crab status -d crabsubmit/crab_cmsdas_zpeak_test0
Once all jobs are finished, print a summary of what was processed:
crab report -d crabsubmit/crab_cmsdas_zpeak_test0
Summary from jobs in status 'finished':
  Number of files processed: 64
  Number of events read: 2167324
  ...
Question 6.5
How many events were read? Enter the number from your
crab reportin the answer form.
Optional: View the Z peak from the combined data
CRAB processed far more events than your local job in Episode 5. Combine the histograms from all output files with
hadd. First find your output folder, which is named after the task’s submission time:eosls /store/user/<username>/DoubleMuon/crab_cmsdas_zpeak_test0/Then list the files with
xrdfsand pass them all tohadd:DIR=/store/user/<username>/DoubleMuon/crab_cmsdas_zpeak_test0/<timestamp>/0000 hadd ZPeak.root $(xrdfs root://cmseos.fnal.gov ls $DIR | grep ZPeak | sed 's|^|root://cmseos.fnal.gov/|')Open
ZPeak.rootand plotzpeak_analyzer/dimuonMassas in Episode 5: there should be many more events. Tip: keep merged files below about 5 GB; many filesystems and networks handle larger files poorly.
Where to find more on CRAB
- CRAB home and CRAB FAQ
- CRAB troubleshooting guide: how to fix common problems and ask for support
- Computing Tools forum on cms-talk: ask for help with job problems (include the task’s HELP URL from
crab status), and follow CRAB and grid announcements
Last reviewed: 2024/10/28 by David Yu
Key Points
CMS data is stored around the world at various T1, T2, and T3 computing sites.
Use the Data Aggregation Service (DAS) to search for CMS data.
The CMS Remote Analysis Builder (CRAB) utility lets you launch jobs on the CMS grid.
Grid jobs run around the world, typically (but not always) using CPUs at the same site as the data.
CMSDAS Pre-Exercise 7: Statistics reading course
Overview
Teaching: 0 min
Exercises: 0 minQuestions
Which statistics concepts should I know before CMSDAS?
Where can I learn them, at my own pace?
Objectives
Learn the basics of each topic in the statistics reading course before CMSDAS.
Run the interactive examples to build intuition.
Optional, but a real head start
- This episode is not required to register for CMSDAS and has no questions to submit, but we strongly encourage everyone to do it.
- Almost every CMSDAS Long exercise ends in a fit, a significance, or a limit. Students who arrive knowing the basic concepts will have a real advantage, instead of learning the statistics under time pressure during the school.
- The same concepts are behind every CMS result you will work on after CMSDAS, so the effort pays off well beyond the school.
- Covering the basics takes steady effort over a few weeks, so start early.
The course
Statistical Methods and Data Analysis Techniques is an online book of reading material on the basic concepts of statistics.
Why this course?
- Written by a CMS physicist, in the language physicists use, and focused on the topics most relevant to HEP analyses.
- Interactive: many sections are Jupyter notebooks you can run and modify in your browser via Binder, with no installation needed.
Acknowledgement
The course is written by Mauro Donegà (ETH Zürich), based on the ETH Zürich master’s course Statistical Methods and Analysis Techniques in Experimental Physics, taught with Christoph Grab and Christian Regenfüs. We thank Mauro for allowing CMSDAS to use this material.
How to use it
Working through the full course at your own pace takes about 3 weeks. You don’t need all of it before CMSDAS: aim to learn the basics of each topic below, and go deeper wherever you are curious or where your analysis will need it.
- Read the book online in order, using the arrows at the bottom of each page, or jump to a topic from the sidebar.
- On notebook pages, click the rocket icon (top right) → Binder to run the code. Binder takes a minute or two to start, and its sessions are temporary: download the notebook (download icon) if you want to keep your changes.
| Topic | Read | Try it interactively |
|---|---|---|
| Probability | Introduction, Probability | Conditional probability, Bayes theorem |
| Distributions | Probability distributions | Random walk |
| Uncertainties | Measurement uncertainties | Error matrix |
| Monte Carlo | Monte Carlo methods | Random numbers with numpy |
| Parameter estimation | Statistical inference, Likelihood, Least squares | ML method: mean of a Gaussian, From least squares to likelihood |
| Hypothesis testing | Hypothesis testing | |
| Confidence intervals and limits | Confidence intervals | Poisson intervals, Upper limit |
| Multivariate analysis | Multivariate analysis methods |
To check your understanding, try the exercises at the end of the book.
Questions and discussion
There is a dedicated Mattermost channel for this course: StatisticsReadingCourse. Please ask questions there, however basic: someone else is probably wondering the same thing, and discussing with other students is a great way to learn. The channel is in the CMSDAS@LPC 2027 Mattermost team; if the link doesn’t open, join the team first (see the setup instructions).
Key Points
The reading course covers the statistics used in HEP analyses: probability, uncertainties, Monte Carlo, likelihood fits, hypothesis tests, and confidence intervals.
Many sections are executable notebooks you can run in your browser with Binder.
Ask questions in the StatisticsReadingCourse Mattermost channel.